BaseDynamics

The Foundational Data Engine

Zero-Taxonomy Product Mapping

Stop wasting engineering cycles instrumenting code and fixing broken schemas. BaseDynamics deploys a product crawler that reads, classifies, and maps your entire product on its own.

Automated Feature ClusteringFrontier Model TaxonomySelf-Healing Event Definitions

Stop instrumenting, try BaseDynamics

Stop manual instrumentation. Start mapping the metrics automatically.

How the Product Crawler Operates

Automatic Interface Scaffolding

The product crawler moves through your knowledge base articles and digital application, inspecting and cataloging every page, flow, and element.

Interface Classification: Scans your entire product to accurately categorize page types and nested views.

Action Mapping: Automatically identifies primary buttons, forms, and core navigation steps.

Instant Time-to-Value: Produces a functional blueprint of your product's architecture in minutes, not months.
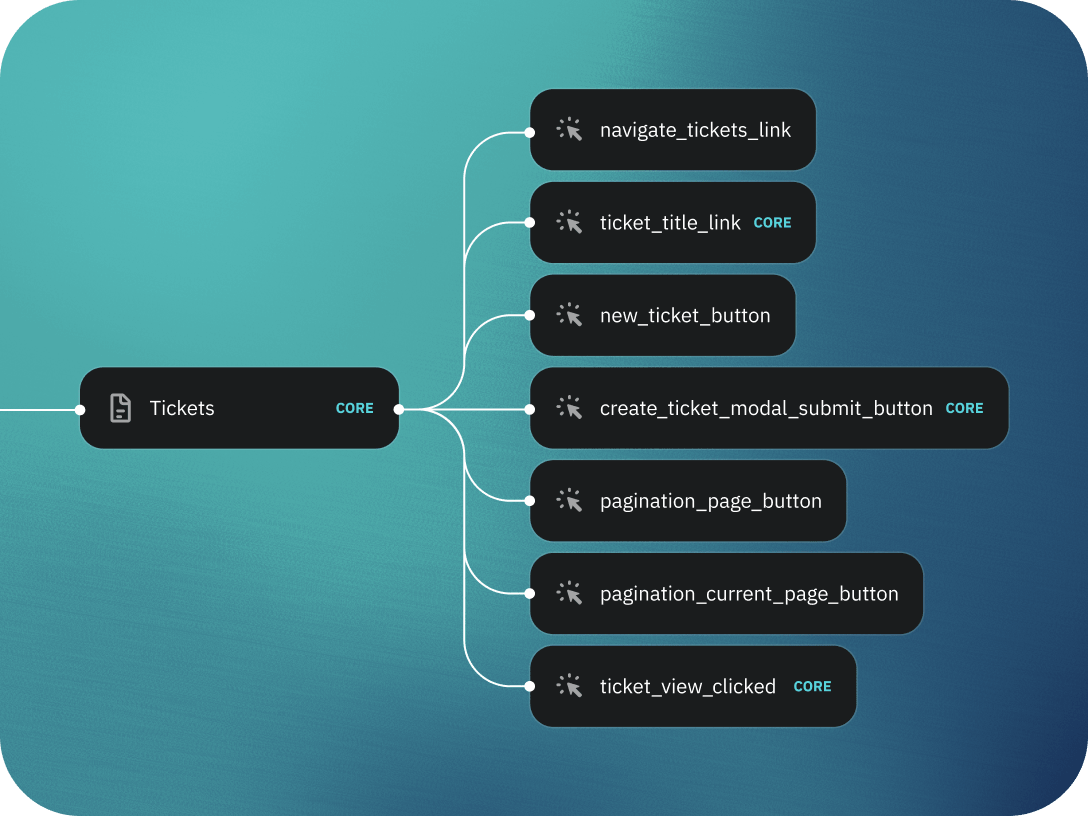
Tickets area mapped to core click events like create, navigate, and view

Semantic Feature Clustering

Frontier models take the definition work off your product and engineering teams.

Dynamic Grouping: Clusters individual page elements and click events into clean, logical product areas.

AI-Generated Taxonomies: Writes clear names and functional descriptions for every discovered event cluster.

Eradicate Schema Drift: Maintains an accurate, human-readable data directory that stays current as your code ships.

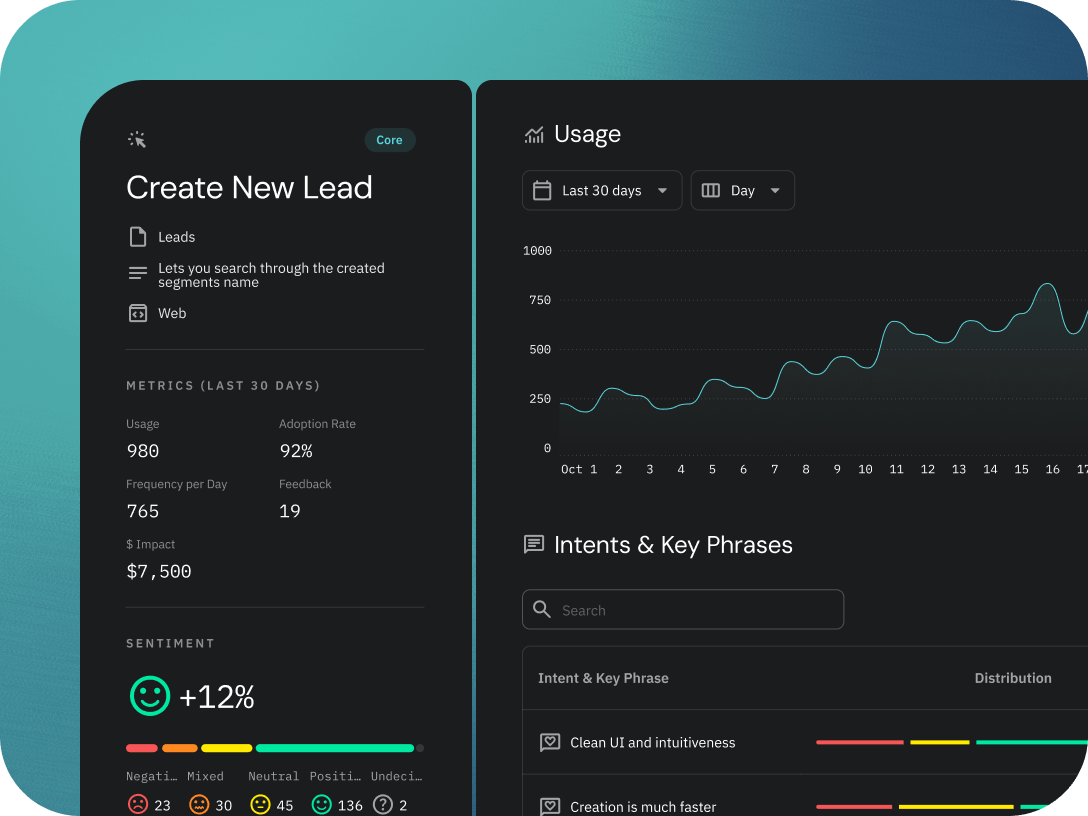
Create New Lead feature with usage, sentiment, and key-phrase clusters

Connected Data Enrichment

Once your interface is mapped, the product crawler aligns telemetry with your commercial systems.

Telemetry Connection: Maps incoming events from Mixpanel, Segment, or DB mirrors directly to the correct feature area.

Customer Voice Sync: Uses vector search to map tickets and call transcripts to the matching product module or event.

CRM Data Overlay: Attaches company records and subscription values to user workflows to track financial impact.

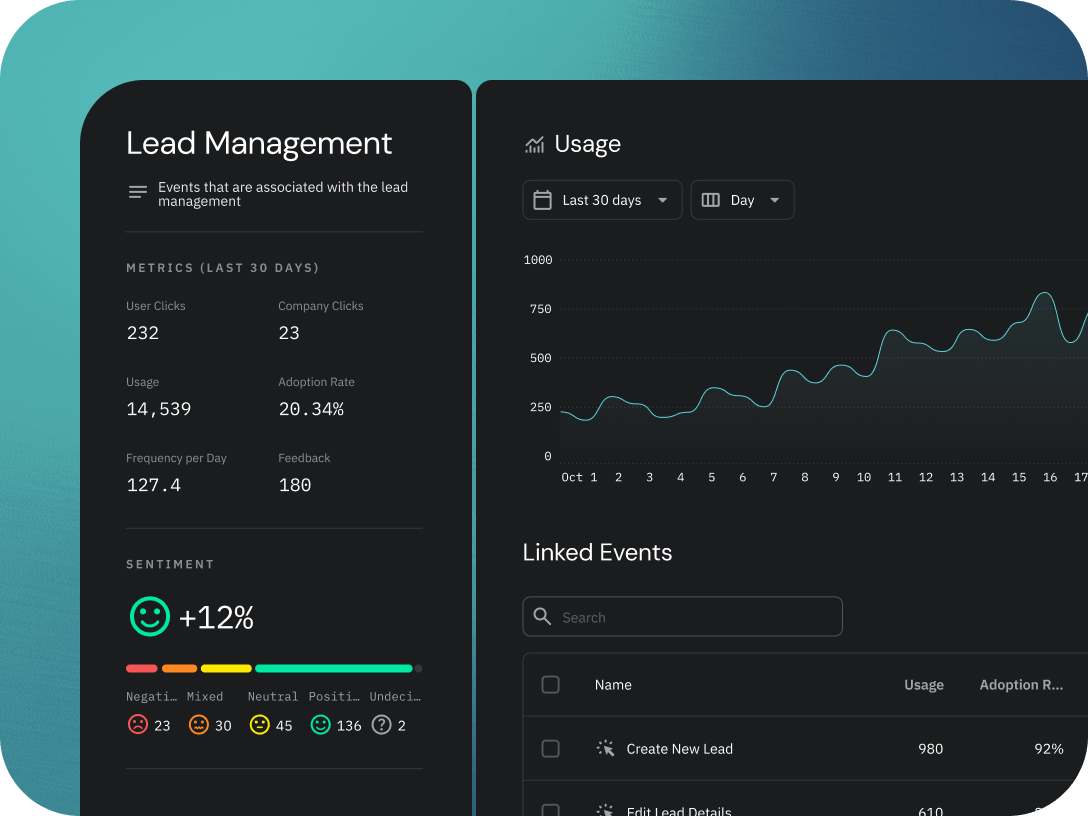
Lead Management area with usage metrics and linked product events

Platform Value & Macro Outcomes

Eliminate Setup Overhead Completely

Traditional CS platforms demand months of expensive data engineering just to define tracking schemas. The BaseDynamics product crawler is entirely self-serve, so you can unlock full portfolio analytics in less than a day, with zero setup.

Self-Healing Release Observability

When your product team ships an update or changes an event property, standard analytics dashboards break. Our product crawler detects changes and flags exceptions automatically, keeping your data guardrails stable.

Grounded Knowledge Graph Foundations

By automatically mapping your application, the product crawler forms the foundation of your customer knowledge graph: a clean structural layer that lets your agents evaluate account health and run plays without tracking gaps.

Got questions?

No. The product crawler reads your existing knowledge base articles, front-end and connected telemetry sources directly, so there's no code to instrument definitions for and no manual tagging queue to maintain before you get usable data.

A tagging plan is a static document your team has to write, maintain, and re-approve by hand. The product crawler is a living system: it classifies your interface, names and groups events using frontier models, and keeps that structure current, with zero to very minimal upkeep.

Stop manual instrumentation

Connect your platform telemetry and let our autonomous product crawler build your customer knowledge graph today.